Faster and More Accurate Alert Adjudication Using LASAA
Created June 2026
As part of the project “Using LLMs to Adjudicate Static-Analysis Alerts” (“LASAA”), we at the SEI designed, implemented, and evaluated LLM-based techniques for adjudicating static-analysis alerts quickly and accurately. After analyzing the results of our evaluation, we concluded that this approach shows great promise.
The Difficulty of Using Static Analysis to Evaluate Source Code
Software vulnerabilities pose a significant risk to critical systems. During development and prior to deployment, software developers and analysts use static analysis to evaluate source code for potential vulnerabilities. Static analysis is widely used and is one of the best techniques available for adjudicating static analysis results. However, it is time-consuming and expensive because it requires significant manual effort, and the volume of findings is often too large to review in its entirety. The result is that software analysts manually adjudicate only the highest priority alerts, which leaves the rest as a significant unknown risk.
Large Language Models (LLMs) are a technology that shows promise for automating alert adjudication. Although older ML techniques lack easy interpretability and often pivot on irrelevant details that merely correlate with code flaws in their training data, newer LLMs are different. These new LLMs produce detailed reasoning that they use to reach their final answers, and these reasoning chains can be manually double-checked. Sometimes these reasoning chains reveal that the LLM initially made a mistake in its analysis but was able to detect and recover from the mistake, eventually reaching the correct answer.
LASAA Is Faster and More Accurate
We are exploring and have developed multiple techniques for using LLMs to handle static analysis output. Recent research indicates that LLMs, especially reasoning models such as o3, o4-mini, and all current frontier models, represent a significant step forward in automated static-analysis adjudication. In one study, researchers could use LLMs to identify more than 250 types of vulnerabilities and reduce the number of those vulnerabilities by 90 percent.
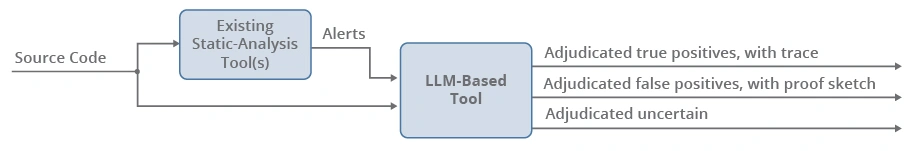
By studying the capabilities of the newer LLMs, we identified ways we can tool LLMs to generate better results. For example, to handle alerts whose adjudication requires analyzing multiple functions spread across the codebase, we leverage LLMs’ ability to generate function preconditions and to check preconditions at callsites. We also found that LLMs perform much better when they are asked to adjudicate a particular issue on a particular line of code rather than prompted to find all the errors in a function. Based on these and other findings, we developed an approach for using LLMs to adjudicate static analysis alerts that we implemented in our LASAA tool.
We developed LLM initial tooling, tested that tooling, and studied the results. We analyzed related work by other researchers and prepared for the direction we would take to further improve our exploration of this topic. LASAA enables more complete alert adjudication, thereby reducing unknown risk and enabling the removal of vulnerabilities before software is fielded. Some LASAA techniques are based on our observation that LLMs rarely answer static-analysis adjudication questions consistently wrong. Instead, when the query is run multiple times, an LLM is likely to either consistently deliver the right answer or deliver inconsistent answers.
How LASAA Works
We tested LASAA on multiple popular LLMs, including some that can be run on-premises (a possible requirement for classified content) and others that run off-site only. We were able to demonstrate that our LLM-based techniques automatically adjudicated a large percentage of alerts with high accuracy on randomly selected sets from three test suites: Juliet C/C++ v1.3, FormAI, and SVCOMP benchmarks. We also tested our techniques on multiple real-world codebases used as modules for ground and space systems, including NASA AMMOS’ Multi-Mission Time Correlation (MMTC) Java code and NASA’s Core Flight System (cFS).
These demonstrations have shown that LASAA potentially enables more secure code, supports mission effectiveness, and reduces support costs.
LASAA is released as open-source software and is available at https://github.com/cmu-sei/lasaa/.
Software and Tools
LASAA Software
LASAA uses a large language model (LLM) to adjudicate static-analysis alerts. It also reports a justification along with every verdict.
Learn MoreLooking Ahead
Looking to the future, LLMs can be used to improve the formal verification of software, an area that currently requires a huge amount of manual effort. Generating and proving loop invariants and function pre-/post-conditions is a crucial and challenging part of formal verification, and LLMs appear promising for helping with this task as well.